Hallucinations of VLMs
Note: That the below is a continuous work in progress. This blog’s ethos of writing posts is elaborated here. All changes can be tracked via the commit history of the markdown file here.
Motivating Question: Why do VLMs hallucinate? Why do they hallucinate more than LLMs? Can we do anything about it?
Partial Inspiration: Lilian Weng’s “Extrapolating Vision-Language Models & Hallucination”
Table of Contents
- What are VLMs?
- How Are They Trained?
- VLM Hallucinations
- Taxonomy of VLM Hallucinations
- Hallucination Detection & Benchmarks
- Mitigation Methods
- Citations
- Appendix: Evaluation Metrics & Benchmark Reference
What are VLMs?
Vision Language Models (VLMs), also frequently termed Large Vision-Language Models (LVLMs) or Multimodal Large Language Models (MLLMs), are models designed to jointly process and reason across visual tokens (images, video frames) and discrete textual tokens. These systems demonstrate impressive zero-shot capabilities across open-ended visual question answering (VQA), dense captioning, OCR parsing, object localization, and visual reasoning. Notable examples include LLaVA, DeepSeek-VL, Qwen2-VL, InternVL, and OLMo.
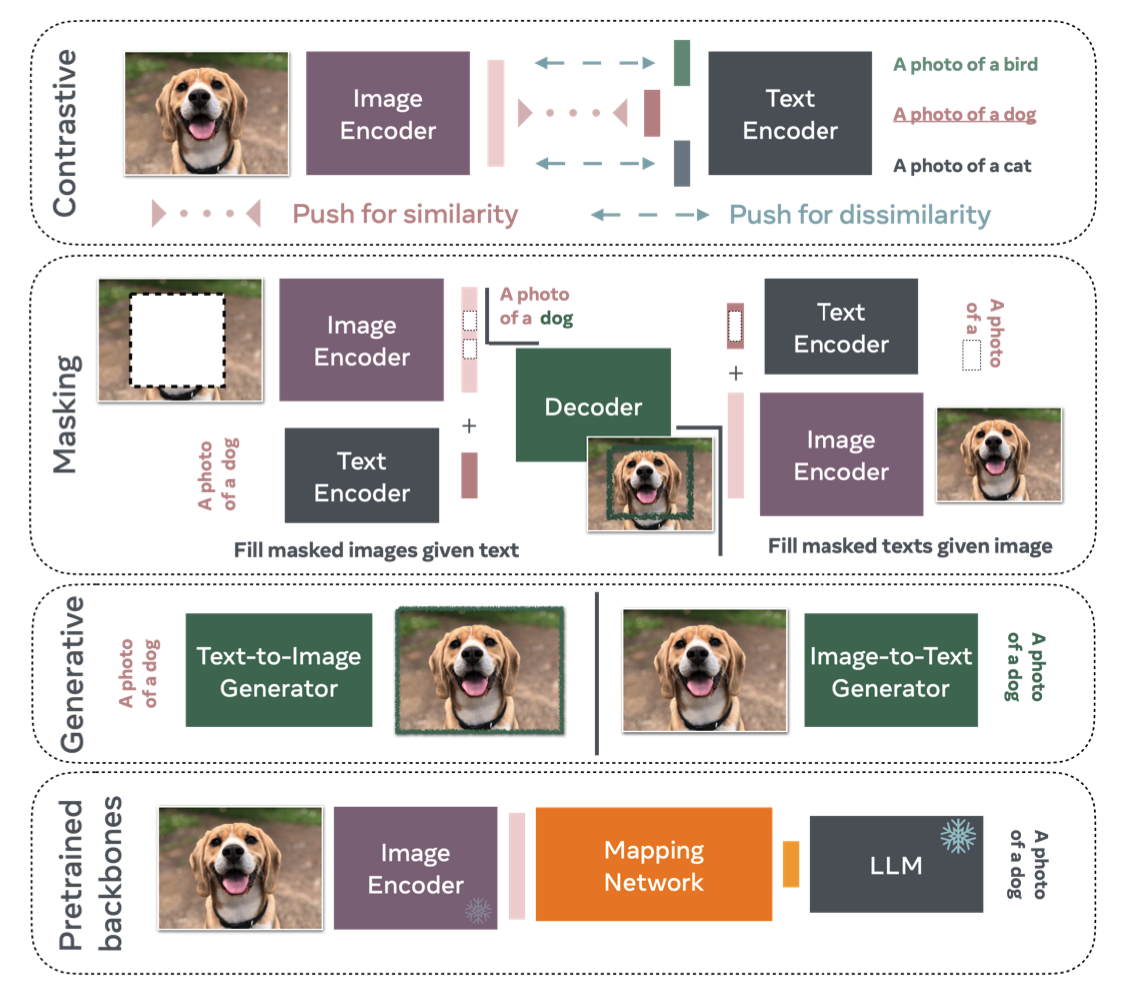
At an architectural level, VLMs fall across distinct paradigms: contrastive, masked reconstruction, and generative autoregressive models [1]. By far the most prevalent and compute-efficient design is the modular backbone architecture:
- A frozen or lightweight-adapted visual encoder (such as CLIP ViT or SigLIP) converts input images into patch embeddings.
- A multimodal projector (a linear projection matrix, MLP resampler, or Perceiver-style cross-attention module) maps visual tokens into the embedding space of a language decoder.
- A pretrained autoregressive LLM (such as Vicuna, LLaMA, or Qwen) consumes the concatenated visual and prefix text tokens to predict response tokens autoregressively.
Because these modular architectures form the foundation of open-source and proprietary multimodal systems today, they will be the primary focus of this post.
How Are They Trained?
Training modular VLMs typically proceeds in two sequential phases:
- Pretraining / Feature Alignment: The visual encoder and language model weights are typically frozen while only the multimodal projector is trained. Using massive corpora of image-caption pairs (such as LAION, COYO, or CC3M), this stage aligns the visual encoder’s latent representations with the language model’s text token space.
- Visual Instruction Tuning: The multimodal projector and language model (often with Parameter-Efficient Fine-Tuning like LoRA, or full fine-tuning) are trained on high-quality visual question-answering pairs and complex conversational traces (e.g., LLaVA-Instruct, ShareGPT4V).
Crucially, the visual front-end (CLIP or SigLIP) is originally trained via a contrastive objective (InfoNCE loss). Contrastive training pairs global image embeddings with global text embeddings, optimizing whether an image matches a candidate caption against batch negatives.
While contrastive objectives capture global semantic alignment, they do not penalize models for ignoring fine-grained spatial configurations, small background objects, or precise relational geometry. The visual feature representation thus enters the multimodal projector coarse and globally biased, laying the foundational substrate for downstream visual hallucinations.
VLM Hallucinations
In pure text LLMs, hallucinations generally manifest as factual inaccuracies or ungrounded assertions driven by parametric memorization errors. In VLMs, the problem is substantially more nuanced and pervasive: the model produces fluent text descriptions that explicitly contradict, invent, or omit entities clearly present or absent in the input image.
VLM hallucinations stem from a fundamental representational asymmetry:
- Latent Space Coarseness: Vision encoders compress high-dimensional, continuous visual scenes into discrete patch tokens, losing high-frequency spatial details.
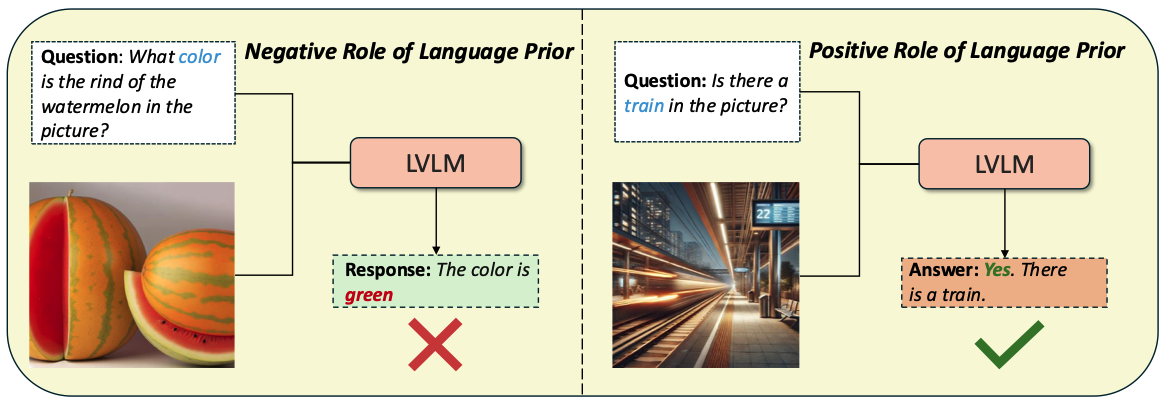
- Language Prior Dominance: The language backbone was pretrained on trillions of tokens of text without vision. Consequently, its parametric language priors are vastly stronger than the signal arriving from a few hundred projected visual tokens.
- Modality Imbalance: Recent studies show that the embedding space utilized by VLMs often lacks a dense, faithful representation of visual tokens, leading language decoders to effectively treat visual inputs as secondary context prompts [2].
Are VLMs More Hallucination-Prone Than LLMs?
Yes. Counterintuitively, giving a model an image often increases its vulnerability to hallucination compared to purely linguistic tasks:
- Fragility to Permutations: VLMs exhibit extreme sensitivity to superficial option shuffling in Multiple Choice Question Answering (MCQA). Permuting candidate choices can cause performance swings of over 20-30%, indicating shallow heuristic reliance rather than robust visual grounding [3].
- Counterfactual Degradation: When presented with visual scenes that counterfactually contradict standard world knowledge (e.g., an unplugged TV being watched, or an upside-down room), VLMs routinely defer to their linguistic priors and claim the television is displaying a show [4].
- Spatial Inversion: On spatial reasoning benchmarks (such as SpatialEval), models frequently exhibit worse performance when provided visual inputs than when given equivalent text descriptions [5].
- Visual “Blindness”: State-of-the-art models fail on simple, low-level visual geometric tasks (e.g., counting line intersections or detecting overlapping geometric shapes) even though the vision encoder holds the necessary features; the language model simply fails to decode them faithfully [2].
Taxonomy of VLM Hallucinations
VLM hallucinations can be decomposed into three primary operational categories:
1. Object-Level Hallucinations
- Existence Hallucination: Claiming an object is present in the scene when it does not exist (e.g., stating there is a dog on the couch when no dog is present).
- Attribute Hallucination: Falsifying fine-grained properties of an actual object, such as color, material, relative size, or physical state (e.g., calling a red car “blue”, or describing a closed door as “ajar”).
- Relational & Spatial Hallucinations: Inverting spatial coordinates or topological relationships (e.g., asserting an object is “to the left of” or “underneath” another when the inverse is true) [5].
- Counting & Numerical Hallucinations: Miscounting identical or clustered entities (e.g., claiming there are five sheep when there are only three).
2. Event, Action & Narrative Hallucinations
- Action & Verb Hallucinations: Fabricating dynamic actions or kinetic verbs that are not occurring in a static scene (e.g., stating a person is “running” when they are standing still) [7].
- Event Hallucinations: Constructing entire fabricated narratives around imagined subjects, hallucinating causal sequences, intent, and interactions that have no visual grounding [8].
3. Modality Conflict & Linguistic Prior Biases
- Modality Conflict: Severe divergence between textual prompt hints and the visual reality in the image, where deceptive prefix prompts coerce the model into abandoning visual grounding [9].
- Language Prior Over-Reliance (LanP): The model anticipates object co-occurrences based on textual world knowledge (e.g., generating “refrigerator” and “microwave” whenever a “kitchen” is identified) regardless of whether those items appear in the visual frame [6], [10].
- Benign Hallucination: When an ungrounded entity mention is incidental and does not corrupt the core factual validity of the final query response.
- Malign Hallucination: When an ungrounded entity leads to incorrect reasoning chains, fatal false assumptions, or safety vulnerabilities.
Hallucination Detection & Benchmarks
Evaluating VLM hallucinations requires distinct methodologies capable of separating reasoning competence from perceptual fidelity. Historically, benchmarks have divided into two paradigms:
- Discriminative Evaluations
- Generative Evaluations
Discriminative Evaluations
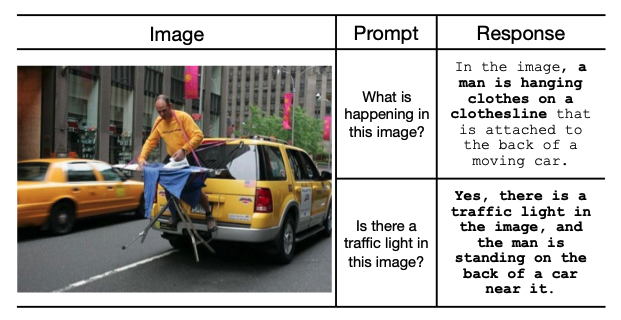
Discriminative benchmarks probe the model with binary Yes/No queries regarding object presence (e.g., “Is there a chair in the image?”).
- Representative Benchmark: POPE (Polling-based Object Probing Evaluation) [12].
- Strengths: Inexpensive to run, deterministic, immune to LLM judge bias, and easy to score.
- Weaknesses: Vulnerable to response-token bias (e.g., models defaulting to “Yes”), misses relational nuance, and fails to evaluate free-form narrative coherence.
Generative Evaluations
Generative evaluations prompt the VLM to produce open-ended descriptive captions or multi-paragraph visual reasoning traces, which are then parsed and evaluated against ground truth annotations.
- Representative Benchmarks: THRONE [11], AMBER [13].
- Strengths: Captures the natural, unconstrained operational regime of conversational assistants.
- Weaknesses: High compute cost and reliance on external LLM evaluators (e.g., GPT-4), which introduces secondary evaluator hallucinations and verbosity biases.
Modern Hybrid Benchmarks
Recent benchmarks bridge the divide between speed and diagnostic depth:
- AMBER [13]: Synthesizes generative captioning and discriminative probing without relying on LLM-as-a-judge evaluators, using the algorithmic AMBER score (grounded in the classic CHAIR metric).
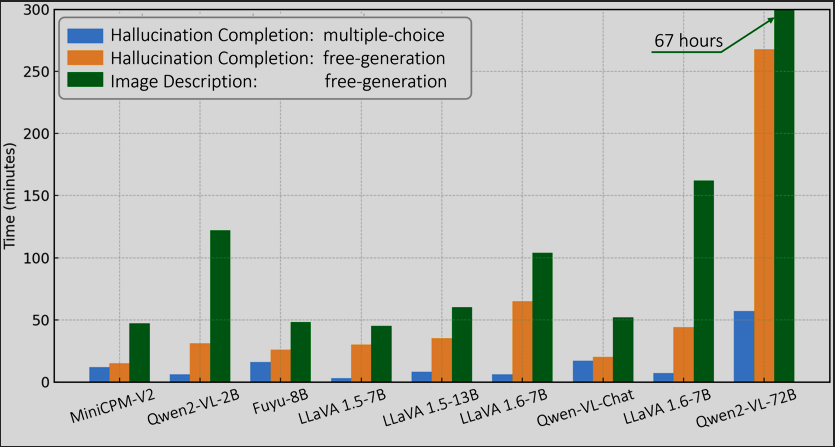
- LongHalQA [11]: Formulates multi-facet visual hallucination probing as high-efficiency Multiple Choice Question Answering (MCQA), slashing evaluation time by orders of magnitude compared to generative pipelines (Fig. 4).
- Dialogue-Level Hallucination: Benchmarks evaluating how hallucinations propagate and compound across multi-turn multimodal conversations [14].
Current Hallucination Mitigation Methods for VLMs
Mitigation strategies currently span four major technical approaches:
1. Visual Direct Preference Optimization (DPO & RLHF)
Post-training preference alignment has emerged as the most potent mechanism to suppress hallucinations without destroying generative fluency:
- HA-DPO (Hallucination-Aware DPO) [15]: Generates positive and negative sample pairs by deliberately injecting and correcting object hallucinations in descriptive text, teaching the model to penalize ungrounded entity mentions.
- V-DPO (Vision-Guided DPO) [16]: Formulates token-level preference optimization using self-calibrated visual-anchored rewards, aligning preference optimization with precise spatial bounding regions.
- CLIP-DPO [17]: Directly leverages the vision-language alignment score of visual encoders as an automated preference oracle, penalizing generated responses that drift semantically from the source image.
- MIA-DPO (Multi-Image Augmented DPO) [18]: Extends preference optimization to multi-image inputs, combating cross-image feature bleeding and temporal hallucination in interleaved sequences.
- On-Policy DPO (OPA-DPO) [19]: Demonstrates that offline negative samples fail to address a model’s true error distribution; training on on-policy model completions provides the sharpest gradient signal for hallucination suppression.
- i-SRT / ISR-DPO (Iterative Self-Retrospective DPO) [20]: Establishes an iterative self-play feedback loop where the model retrospectively critiques and refines its own visual descriptions without requiring external human annotations.
2. Decoding-Time Interventions & Contrastive Decoding
Rather than modifying model weights, decoding interventions manipulate output token probabilities during generation:
- IBD (Image-Biased Decoding) [21]: Contrasts the output logits of a standard VLM forward pass against an image-degraded or text-only forward pass. By subtracting the text-only logits, IBD amplifies true image-grounded tokens and cancels out linguistic priors.
- Visual Contrastive Decoding (VCD): Contrasts logits generated from the original image against logits generated from a visually distorted (blurred/noised) image, directly penalizing language-model drift.
- Summary-Guided Decoding (SUMGD) [22]: Generates an initial concise visual summary to constrain the search space before expanding into detailed long-form generation, keeping the decoder anchored to verified entities.
- Layer-Contrastive Decoding (DoLa / OPERA): Exploits the observation that visual grounding is concentrated in intermediate Transformer layers, contrasting early-layer logits with late-layer logits to suppress hallucinated tokens.
3. High-Quality Instruction Tuning & Data Curation
Addressing hallucination at the source involves eliminating noisy web captions from instruction datasets:
- Dense Synthetic Grounding: Replacing noisy alt-text with detailed, machine-generated grounded captions (e.g., ShareGPT4V).
- Counterfactual Fine-Tuning: Incorporating synthetic negative samples where models are penalized for confirming non-existent objects.
4. Attention Calibration & Post-Hoc Verification
- Attention Re-weighting: Tracking attention weights between generated tokens and visual patch tokens; when cross-attention to visual tokens dips below a threshold, the model is penalized or steered to re-attend to visual features.
- Post-Hoc Verification (e.g., Woodpecker): Multi-agent post-processing pipelines where a secondary vision expert (e.g., an open-vocabulary object detector like Grounding DINO) verifies every extracted entity in the generated response and edits discrepancies prior to user display.
Citations
[1] Bordes, F., Pang, R. Y., Ajay, A., Li, A. C., Bardes, A., Petryk, S., Mañas, O., Lin, Z., et al. (2024). An Introduction to Vision-Language Modeling. arXiv preprint arXiv:2405.17247.
[2] Rahmanzadehgervi, P., Bolton, L., Taesiri, M. R., & Nguyen, A. T. (2024). Vision language models are blind: Failing to translate detailed visual features into words. arXiv preprint arXiv:2407.06581.
[3] Zong, Y., Yu, T., et al. (2023). Fool Your (Vision and) Language Model With Embarrassingly Simple Permutations. arXiv preprint arXiv:2310.01651.
[4] Parcalabescu, L., et al. (2023). What If the TV Was Off? Examining Counterfactual Reasoning Capabilities of Multi-Modal Language Models. arXiv preprint arXiv:2310.06627.
[5] Wang, J., Ming, Y., Shi, Z., Vineet, V., Wang, X., Li, Y., & Joshi, N. (2024). Is A Picture Worth A Thousand Words? Delving Into Spatial Reasoning for Vision Language Models. arXiv preprint arXiv:2406.14852.
[6] Wu, Z., Niu, Y., Gao, H., Lin, M., et al. (2025). LanP: Rethinking the Impact of Language Priors in Large Vision-Language Models. arXiv preprint arXiv:2502.12359.
[7] Liu, Y., et al. (2024). Action and Verb Hallucinations in Multimodal Large Language Models. arXiv preprint arXiv:2412.14487.
[8] Tian, J., et al. (2024). Hal-Eval: A Universal and Fine-grained Hallucination Evaluation Framework for Large Vision-Language Models. arXiv preprint arXiv:2402.15721.
[9] Liu, J., et al. (2024). PhD: A ChatGPT-Prompted Visual Hallucination Evaluation Dataset. arXiv preprint arXiv:2403.11116.
[10] Datta, S., & Sundararaman, D. (2025). Evaluating Hallucination in Large Vision-Language Models based on Context-Aware Object Similarities. arXiv preprint arXiv:2501.15046.
[11] Kaul, P., Li, Z., Yang, H., et al. (2024). THRONE: An Object-based Hallucination Benchmark for the Free-form Generations of Large Vision-Language Models. arXiv preprint arXiv:2405.05256.
[12] Li, Y., et al. (2023). Evaluating Object Hallucination in Large Vision-Language Models. Empirical Methods in Natural Language Processing (EMNLP 2023). arXiv:2305.10355. GitHub: RUCAIBox/POPE.
[13] Wang, J., et al. (2023). An LLM-free Hallucination Benchmark for Multimodal Large Language Models. arXiv preprint arXiv:2311.07397.
[14] Zhao, Y., et al. (2024). Evaluating Dialogue-Level Hallucinations in Multimodal Large Language Models. Findings of the Association for Computational Linguistics (EMNLP 2024). ACL Anthology.
[15] OpenDataLab. (2023). Beyond Hallucinations: Enhancing LVLMs through Hallucination-Aware Direct Preference Optimization. arXiv preprint arXiv:2311.16839. Project: HA-DPO.
[16] Sun, X., et al. (2024). V-DPO: Mitigating Hallucination in Large Vision Language Models via Vision-Guided Direct Preference Optimization. arXiv preprint arXiv:2411.02712.
[17] Ouali, Y., et al. (2024). CLIP-DPO: Vision-Language Models as a Source of Preference for Fixing Hallucinations in LVLMs. arXiv preprint arXiv:2408.10433.
[18] Liu, Z., et al. (2024). MIA-DPO: Multi-Image Augmented Direct Preference Optimization For Large Vision-Language Models. arXiv preprint arXiv:2410.17637.
[19] Yang, Z., Luo, X., Han, D., Xu, Y., & Li, D. (2025). Mitigating Hallucinations in Large Vision-Language Models via DPO: On-Policy Data Hold the Key. Computer Vision and Pattern Recognition (CVPR 2025). arXiv:2501.09695.
[20] Ahn, D., Choi, Y., Kim, S., Yu, Y., Kang, D., & Choi, J. (2024). i-SRT: Aligning Large Multimodal Models for Videos by Iterative Self-Retrospective Judgment (ISR-DPO). arXiv preprint arXiv:2406.11280.
[21] Zhu, L., Ji, D., Chen, T., Xu, P., Ye, J., & Liu, J. (2024). IBD: Alleviating Hallucinations in Large Vision-Language Models via Image-Biased Decoding. arXiv preprint arXiv:2402.18476.
[22] Min, K., Kim, M., Lee, K., Lee, D., & Jung, K. (2024). Mitigating Hallucinations in Large Vision-Language Models via Summary-Guided Decoding. arXiv preprint arXiv:2410.13321.
[23] Rohrbach, A., Hendricks, L. A., Burns, K., Chattopadhyay, P., Saenko, K., & Darrell, T. (2018). Object Hallucination in Image Captioning. Empirical Methods in Natural Language Processing (EMNLP 2018). arXiv:1809.02156.
Appendix: Evaluation Metrics & Benchmark Reference
1. Mathematical Formulations of Key Metrics
CHAIR (Caption Hallucination Assessment with Image Relevance)
Introduced by Rohrbach et al. [23], CHAIR evaluates object hallucination in free-form generated text by matching generated object words against ground-truth MSCOCO segmentations:
- Instance-Level (
CHAIR_i): The fraction of hallucinated object instances out of all mentioned object instances:
\text{CHAIR}_i = \frac{|\{\text{hallucinated objects}\}|}{|\{\text{all mentioned objects}\}|}
- Sentence-Level (
CHAIR_s): The fraction of generated sentences containing at least one hallucinated object:
\text{CHAIR}_s = \frac{|\{\text{sentences with hallucinated objects}\}|}{|\{\text{total sentences}\}|}
POPE Sampling Strategies
The POPE benchmark [12] probes binary existence using three distinct negative sampling regimes to test different degrees of bias:
- Random: Non-existent objects are sampled uniformly at random from candidate datasets.
- Popular: Negative objects are sampled from the most frequent global classes in the dataset (testing high-frequency prior bias).
- Adversarial: Negative objects are sampled from classes that frequently co-occur with the present objects in training corpora but are absent from the specific query image (testing contextual co-occurrence bias).
2. Comprehensive Benchmark Comparison
| Benchmark | Evaluation Mode | Format | Evaluator Dependency | Primary Target |
|---|---|---|---|---|
| POPE [12] | Discriminative | Binary Yes/No questions | Rule-based (exact match) | Object existence & co-occurrence bias |
| CHAIR [23] | Generative | Image captioning | Synset / Lemmatization matching | Free-form object hallucination rate |
| AMBER [13] | Hybrid | Generative descriptions + Discriminative queries | Algorithmic (AMBER / CHAIR score) | Holistic hallucination without LLM judges |
| THRONE [11] | Generative | Open-ended free generation | LLM-as-a-judge (GPT-4) | Object and relation grounding in rich text |
| LongHalQA [11] | Hybrid / Fast | Multiple Choice QA | Direct choice matching | Fast hallucination probing at scale |
| PhD [9] | Discriminative | Standard, inaccurate & counter-common-sense VQA | Structured rule match | Text-image modality conflicts & deceptive context |
| Hal-Eval [8] | Hybrid | Fine-grained multi-facet evaluation | Hybrid parser & judge | Complex event, attribute, and relational hallucinations |